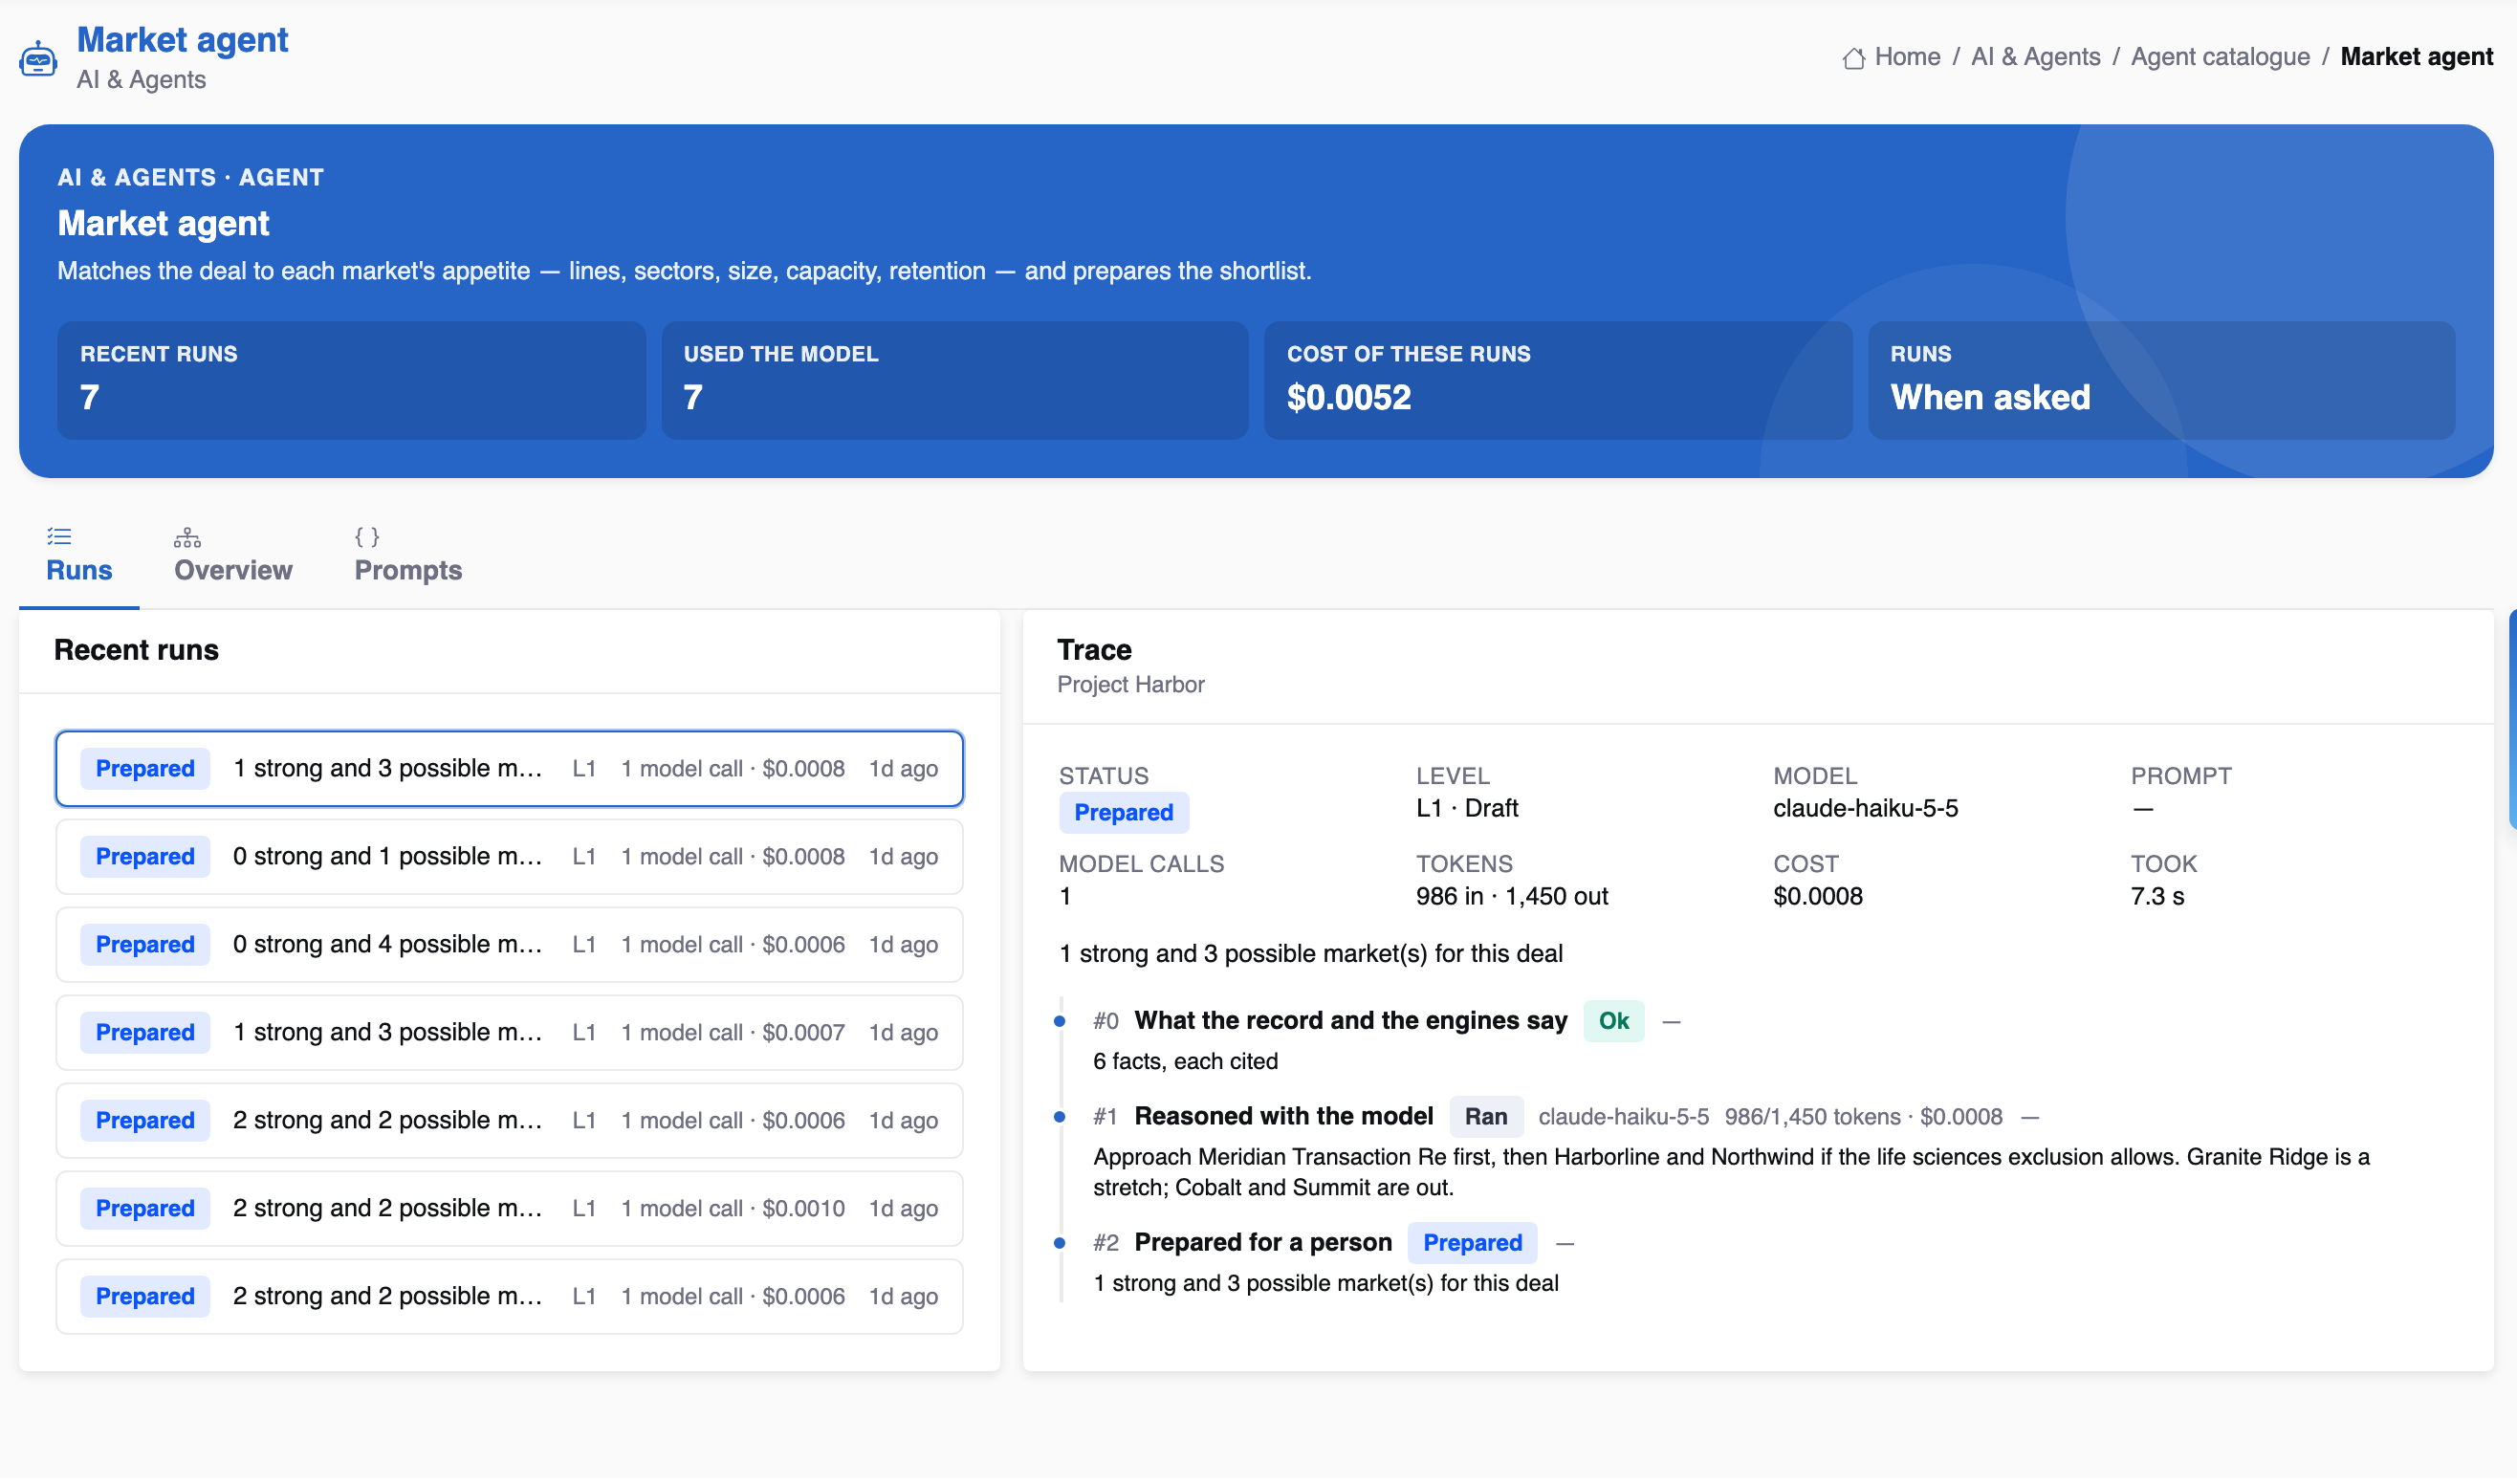
A model-risk or compliance reviewer asks the same questions of any AI in a regulated business: what does it do, what can it not do, how do you know, and where is the evidence. Here is where InsightDealDesk keeps each answer.
| Question | Where the answer lives |
|---|---|
| What can the agents do? | The catalogue: eleven agents, their actions and their levels. Five actions, all capped at ask-first. |
| Can a model invent a figure? | The grounding check: any number not among the cited facts rejects the answer; engines own every figure. |
| What did a model see and say? | A Lense trace per step: model, tokens, cost, seconds, facts, output, stray numbers. |
| Which prompt? | Prompts versioned in InsightPrompts, with local defaults. |
| Who decided? | The decision record: every answer signed, every sign-off by a practice leader. |
| Who could see the deal? | Book scope: brokers see their own deals; leads see the practice; the copilot re-checks scope per tool. |
| What does it cost? | Per-step cost in the trace; per-agent daily budgets and a circuit breaker on the model. |
| Do the tests call a model? | No. A guard refuses Bedrock in tests and counts attempts; reasoning is tested with an injected transport. |
flowchart TB
P["Prompt, versioned"] --> M["Model call on Bedrock,
in your AWS account"] F["Facts, cited"] --> M M --> G["Grounding check"] G --> T[("Lense trace")] G --> PD["Prepared decision"] PD --> H["Human answer"] H --> DR[("Decision record")] H --> AU["Autonomy evidence"]
in your AWS account"] F["Facts, cited"] --> M M --> G["Grounding check"] G --> T[("Lense trace")] G --> PD["Prepared decision"] PD --> H["Human answer"] H --> DR[("Decision record")] H --> AU["Autonomy evidence"]
sequenceDiagram
participant R as Reviewer
participant AC as Agent catalogue
participant TR as Trace
participant DR as Decision record
R->>AC: What may the quote agent do?
AC-->>R: Select quote, capped L2
R->>TR: Show the run on Project Alder
TR-->>R: Facts, model, tokens, output
R->>DR: Who accepted?
DR-->>R: Broker, time, note
Keep reading
How it works
The Deal Workspace: one page per deal
The stage strip, the agents' work on top, and every figure one click from its page.
Read article
How it works
Eleven deal agents, inside a broker's authority
Read the data room, predict the exclusions, match the markets, compare the quotes, check the binder.
Read article